Hajed
Khlifi

GPU & AI Infrastructure Architect · HPC, Slurm, Kubernetes

I'm a hands-on architect for GPU and HPC infrastructure. I design NVIDIA GPU clusters, Slurm and Kubernetes platforms and LLM inference stacks, and I still build the proofs of concept myself. Much of my recent work is in life sciences: HPC platforms for Sanofi and Syngenta, and AI workload profiling across about 22 Pfizer R&D teams for NVIDIA. I'm as comfortable leading a client workshop as tuning a scheduler, in English, French or Arabic.

NVIDIA NVIDIA NCP-AIO K8s CNCF Kubestronaut ☁ AWS / GCP Architect 🎤 International Speaker 🧬 Life Sciences HPC
Hajed Khlifi, GPU and AI infrastructure architect
8+ Years Experience
10+ Certifications
20+ Conferences participation
8+
Years in DevOps, Cloud & Platforming
10+
Professional Certifications
7
Conference Talks
3
Languages Spoken

GPU · HPC · AI infrastructure

I build the GPU clusters and platforms that AI teams run on.

From NVIDIA cluster design and Slurm and Kubernetes scheduling to LLM inference and GPU cost visibility, for life sciences, research and regulated industries.

2,048NVIDIA B300 GPUs in the AI factory I advise on
~22pharma R&D teams profiled for NVIDIA
3global life-sciences clients: Sanofi, Syngenta, Pfizer
H200 · B300NVIDIA platforms I have designed for

GPU & AI Infrastructure Services

End-to-end architecture, from GPU cluster design to production Slurm and Kubernetes platforms, for life sciences, research and regulated European markets.

🔸
GPU Cluster Architecture
Design GPU clusters and AI factories on NVIDIA HGX H200 and B300 and DGX systems: fabrics, storage, power per rack, and vendor quotes reviewed line by line against NVIDIA reference designs. Then the NVIDIA AI stack on top: GPU Operator, CUDA, MIG and vLLM.
NVIDIA H200 DGX Systems Cisco UCS CUDA MIG
☵
Kubernetes & Cloud Native
Architect and automate large-scale Kubernetes platforms with custom operators, Helm charts, and GitOps pipelines. OpenShift, GKE, GDCH, and bare-metal deployments across hybrid environments.
Kubernetes OpenShift Operators Helm ArgoCD
🔒
Sovereign & Air-Gapped Cloud
Build secure, sovereign cloud platforms for European government and regulated clients. Air-gapped deployments, Google Distributed Cloud Hosted (GDCH), PKI, Vault, and full compliance frameworks.
GDCH Air-Gapped Vault PKI Compliance
🤖
AI Platform Deployment
Deploy production-grade AI suites including Mistral AI, RAG systems, Agentic AI, and LLM orchestration. Triton Inference Server, RAPIDS, vector databases, and AI Studio integration.
Mistral AI RAG Triton vLLM Vector DB
CI/CD
DevOps & Automation
Infrastructure as Code with Terraform and Ansible. CI/CD pipelines with GitLab CI, ArgoCD, and Tekton. Full observability stacks with Prometheus, Grafana, and ELK.
Terraform Ansible GitLab CI Prometheus Grafana
🎓
Advisory, Workshops & Enablement
Discovery workshops, architecture reviews, HLD and LLD, TCO and executive readouts. I translate scientific and regulatory needs (GxP, sovereignty) into designs teams can build, and coach engineers and partners to run them.
Workshops Demos Advisory Architecture Review

Professional Experience

From deployment analyst to principal architect, a trajectory built on deep hands-on infrastructure expertise.

Quantori 2026 – Present
HPC Solutions Architect
Luxembourg, Luxembourg · Remote
  • Designing and delivering HPC and GPU platforms for biopharma and agri-science R&D clients: Pfizer, Sanofi, Syngenta and other life-sciences organizations.
  • Lead HPC Cloud Architect on a global pharma HPC fabric program: AWS ParallelCluster + Slurm for tightly-coupled workloads (Schrödinger, CryoEM), AWS Batch + Nextflow for containerized pipelines, FSx for Lustre scratch, and Prometheus/Loki/Grafana observability.
  • Leading an HPC strategy and design discovery engagement: target architecture, GPU buy-vs-rent sourcing strategy, TCO model, and executive roadmap.
  • Ran structured AI workload profiling across ~22 pharma R&D teams for NVIDIA, turning interviews into workload matrices and a C-level findings deck.
  • Building production Terraform IaC for AWS HPC with observability and cost controls built in.
  • Designed licence-aware scheduling: a FlexLM poller feeds Slurm remote licenses and AWS Batch so jobs wait for a licence instead of failing mid-run.
  • Run technical interviews and coach the team on Slurm and AWS HPC.
LIAN Group 2026
NVIDIA Infrastructure Advisor (part-time / one shot)
Covilhã, Portugal · Remote
  • Client-side technical lead on LUME Cluster 1, a 2,048-GPU NVIDIA HGX B300 AI factory (256 nodes), working between Computacenter, NVIDIA and i3D.net.
  • Reviewed the bill of materials line by line against NVIDIA reference designs and defined the specs the quote must carry: compute nodes, compute and storage fabrics, storage tier and management stack.
Proximus Luxembourg 2025 – 2026
Principal Solution Architect · Cloud & AI
Luxembourg, Luxembourg
  • Promoted to lead the infrastructure team. Driving end-to-end deployment of a high-density H200 GPU cluster on Cisco C885A servers for European clients.
  • Mastered the full NVIDIA AI stack (GPU Operator, CUDA) with Harvester/Rancher to expand GPU capacity and deploy production-grade Mistral AI suites.
  • Architected and automated large-scale, secure Kubernetes platforms using custom operators, enabling scalable RAG, Agentic AI, and AI inference systems for EU clients.
  • Coaching the team through technical workshops and documentation. Full lifecycle solution delivery including on-site support.
Proximus Luxembourg 2025
Solutions Architect
Luxembourg, Luxembourg
  • Led the strategic design of secure, sovereign cloud and AI platforms for European government clients as a trusted technical advisor.
  • Architected and deployed production-grade AI infrastructure with Mistral AI on air-gapped platforms with NVIDIA GPUs for large-scale inference and RAG systems.
  • Designed and automated Kubernetes environments on Google Distributed Cloud Hosted (GDCH) and OpenShift with custom operators.
  • Applied cloud-native best practices as a Google Cloud Partner consultant for high-availability enterprise architectures.
Sfeir Luxembourg 2024 – 2025
Senior DevOps & Cloud Consultant
Luxembourg, Luxembourg
  • Conducted demos for OpenShift AI, deploying and managing LLM models to validate scalable AI workload orchestration.
  • Upgraded production OpenShift clusters from v4.8 to v4.14 on VMware infrastructure.
  • Architected and automated infrastructure solutions, reducing manual operations by 40% with autoscaling to meet business SLAs.
  • Mentored development teams in designing highly available, large-scale microservices architectures on OpenShift.
VERMEG · Banking & Insurance 2021 – 2023
DevOps Lead Engineer
Tunis, Tunisia
  • Architected and deployed scalable AWS infrastructure (VPC, EC2, EKS, RDS) for data-intensive banking microservices.
  • Managed and optimized Kubernetes clusters on AWS EKS for containerized data-driven applications.
  • Enhanced GitLab CI/CD pipelines and implemented ArgoCD for GitOps deployment workflows.
VERMEG · Banking & Insurance 2020 – 2021
Deployment Analyst · DevOps
Tunis, Tunisia
  • Architected and managed foundational Linux infrastructure for high-availability systems.
  • Led a SaaS migration POC using Docker and Kubernetes for containerized high-availability solutions.
  • Developed automation scripts to streamline deployments and managed production releases for major clients (BNP, Cardif, MAIF).
VERMEG · Banking & Insurance 2019 – 2020
Software Developer · Solife
Tunis, Tunisia
  • Backend Java developer on Solife, a multi-framework JEE life & health insurance platform managing policies, claims, accounting, reinsurance, and reporting end-to-end.
  • Bug fixing and L2 support across the application, including Spring IOC runtime and ORM configuration (Hibernate Core & Tools).
  • JVM tuning and macro-benchmarking (JFR, JMC) with L2 cache management (Ehcache) for high-availability cluster modes.
  • Implemented GDPR/cloud compliance changes (log masking, service externalization, cache replication) and upgraded JBoss/WildFly application servers.
  • Configured HA topologies on Red Hat JBoss and integrated messaging via Spring JMS, MDBs, and ActiveMQ.

Certifications

Industry-recognized certifications across NVIDIA AI, Kubernetes, and major cloud platforms.

Quantori
🏆 1st Place · Quantori AI Hackathon 2026
Quantori · Team "Golden SMILES"
July 2026
Won a 48-hour non-stop company-wide challenge with the Target Triage Copilot, a multi-agent system that triages drug-discovery targets, chaining LangGraph agents over RDKit, ChEMBL and PubMed to score and rank candidates for scientists.
LangGraph Agentic AI RDKit ChEMBL PubMed
NVIDIA AI Infrastructure
NVIDIA AI Infrastructure Professional (NCP-AII)
NVIDIA
In Progress
DGX Systems InfiniBand Base Command Networking Storage
NCP-AIO
NVIDIA AI Operations Professional (NCP-AIO)
NVIDIA
2026
CUDA Fabric Manager GPU Operator Run:ai Slurm MIG
Kubestronaut
Kubestronaut (Kubernetes Champion)
CNCF · Cloud Native Computing Foundation
2025
CKA CKS CKAD KCNA KCSA
Google Cloud Architect
Google Professional Cloud Architect
Google Cloud
2025
GKE Cloud Run IAM VPC BigQuery
Prometheus Certified Associate
Prometheus Certified Associate (PCA)
Linux Foundation
2024
PromQL Alertmanager Grafana Exporters Service Discovery
AWS Solutions Architect
AWS Solutions Architect Associate
Amazon Web Services
2023
EC2 EKS VPC RDS S3 IAM

Technical & Soft Skills

A deep, hands-on stack spanning GPU infrastructure, HPC, AI platforms and cloud native, and the client-facing skills to deliver it.

🔸
NVIDIA Platform
GPU Operator DGX Systems CUDA DOCA DCGM HGX B300 / H200 MIG vLLM Triton Server RAPIDS NCP-AIO
🤖
AI Infrastructure
Mistral AI Claude API RAG Systems AI Studio LLM Orchestration Vector Databases Agentic AI
☵
Kubernetes & Orchestration
Kubestronaut Helm Custom Operators OpenShift GKE CSI / CNI Harvester Slurm Kueue Slinky Rancher
☁
Cloud Platforms
GDCH / GDCA GCP AWS AWS ParallelCluster AWS Batch OpenStack Sovereign Cloud
⚙
Infrastructure & Automation
Terraform Ansible Python Bash Cisco UCS/M8
🔒
Security & Observability
HashiCorp Vault Keycloak PKI Prometheus Grafana ELK Stack GitLab CI ArgoCD Tekton
🤝
How I Work: Client-Facing & Soft Skills
Client discovery workshops Presales & solution design Executive readouts Aligning vendors & partners on one design Translating science needs into architecture HLD / LLD & technical writing Tenders & proposals Mentoring & technical interviews Public speaking Hands-on POCs English · French · Arabic

Languages

English Fluent
French Native
Arabic Native

Featured Projects

Select engagements showcasing GPU infrastructure, Kubernetes platforms, AI deployments, and cloud-native engineering at scale.

🖥
2,048-GPU NVIDIA B300 AI Factory · Portugal
Client-side technical lead on LUME Cluster 1: 256 HGX B300 nodes, 2,048 GPUs. Reviewed the bill of materials against NVIDIA reference designs, defined fabrics, storage and management stack, checked power per rack, and caught a management software support gap before purchase.
NVIDIA HGX B300 AI Factory BOM Review Fabrics Power & Cooling
🧪
Pharma HPC Fabric · Scientist Workbench
Compute layer replacing a legacy GxP pipeline platform. Schrödinger FEP+ and Cryo-EM on Slurm with AWS ParallelCluster, omics pipelines on AWS Batch with Nextflow, FSx for Lustre and S3, with Prometheus, Loki and Grafana and per-job cost for chargeback.
Slurm AWS ParallelCluster AWS Batch Nextflow FSx for Lustre
🌱
HPC Strategy & Design · Agri-Science
Five-week discovery: assessed two on-prem Slurm sites, defined the target architecture, GPU buy-vs-rent sourcing and TCO model, and built a POC federating Slurm across AWS and on-prem behind Open OnDemand. Closed on plan with a follow-on SOW.
Slurm Federation Hybrid HPC TCO Open OnDemand
📊
AI Workload Profiling for NVIDIA · Pharma
Structured profiling across about 22 pharma R&D teams, turning interviews into GPU demand matrices and a findings deck presented to NVIDIA leadership.
Workload Profiling GPU Demand Life Sciences NVIDIA
🐦
Flock · GPU Scheduling & Cost Platform
Founder, in development. Submit jobs to many Slurm and Kubernetes clusters, cloud or on-prem, and see what each job really cost by joining scheduler accounting with GPU telemetry. SaaS or self-hosted.
Slurm Kubernetes DCGM FinOps SaaS
🔑
Licence-Aware Scheduling · Slurm & AWS Batch
A poller reads FlexLM every minute for Schrödinger, MATLAB, gPROMS and Monolix tokens and feeds Slurm remote licenses and AWS Batch, so jobs wait instead of failing mid-run. Became the talk "Slurm Already Solved This" for KubeCon Europe 2027.
FlexLM Slurm AWS Batch Kueue
⚡
GPU Usage Profiler in CUDA
Works out who used each GPU, when, and what it cost, from Slurm and Kubernetes records. The heavy maths runs on the GPU with CuPy and two hand-written Numba CUDA kernels, checked against a NumPy reference. In progress.
CUDA CuPy Numba Slurm Kubernetes
🔀
Multi-Cluster Slurm Gateway
Proof of concept: users submit once and the gateway picks the Slurm cluster from live Prometheus metrics, including queue depth, free GPUs and partition load.
Slurm Prometheus Python Multi-Cluster
🧠
KubeBrain · Multi-Agent Kubernetes AI Assistant
AI-powered Kubernetes management system built on CrewAI and MCP. Four specialized agents: Teacher, Investigator, Inspector, Executor, collaborate through workflow crews to diagnose cluster issues, validate configurations, explain concepts, and safely execute operations.
CrewAI MCP Python Streamlit Kubernetes Agentic AI
🖥
H200 GPU Cluster · EU Sovereign Cloud
End-to-end design and deployment of a high-density NVIDIA H200 GPU cluster on Cisco C885A servers. Full NVIDIA AI stack (GPU Operator, CUDA, MIG) with Harvester/Rancher running production Mistral AI inference and fine-tuning workloads at scale for European enterprise clients.
NVIDIA H200 Cisco C885A GPU Operator Mistral AI Harvester MIG
🔒
Air-Gapped AI Platform · Government
Architected full-stack sovereign cloud on Google Distributed Cloud Hosted (GDCH): compute, networking, IAM, storage, and Kubernetes with custom operators. NVIDIA GPU-powered Mistral AI suite (Mistral Large, Codestral, embeddings) for inference, RAG, and semantic search in fully isolated environments.
GDCH Air-Gapped NVIDIA GPU Mistral Large RAG OpenShift
⚙
Insurance Policy ETL · Event-Driven Batch Platform
Kubernetes-native serverless ETL platform for insurance policy extraction and transformation. Spring Batch jobs auto-scaled with KEDA and Knative on event-driven triggers, deployed via Tekton CI/CD pipelines and ArgoCD GitOps. Fully automated infrastructure provisioning with Terraform, Ansible, and Helm.
Spring Batch KEDA Knative Tekton ArgoCD Terraform
🚀
Dapr-Powered HA Microservices Platform
Implemented Dapr (Distributed Application Runtime) as a sidecar-based runtime to simplify service-to-service invocation, state management, pub/sub messaging, and distributed tracing across a large-scale microservices environment, enabling high availability and cloud portability without vendor lock-in.
Dapr Kubernetes Pub/Sub State Management OpenShift Observability
☵
Kubernetes Platform · Enterprise Scale
Architected large-scale Kubernetes platforms with custom operators, integrated observability, and standardized deployment patterns. Powers scalable RAG, Agentic AI, and LLM serving pipelines with reusable platform components adopted across multiple engineering teams.
Kubernetes Custom Operators OpenShift Helm ArgoCD
☁
AWS Banking Microservices · VERMEG
Led the architecture of scalable AWS infrastructure (VPC, EC2, EKS, RDS) for data-intensive banking microservices. GitOps deployment with ArgoCD and optimized EKS clusters serving demos and POCs for major financial clients including BNP, Cardif, and MAIF.
AWS EKS Terraform ArgoCD GitLab CI RDS

International Speaking

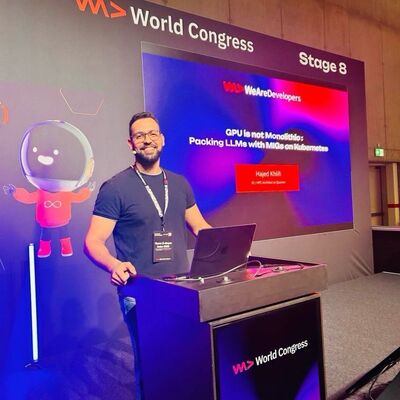
Sharing knowledge on GPUs, HPC and cloud-native infrastructure at conferences across Europe and the US. Talks include "GPU is not Monolithic: Packing LLMs with MIGs on Kubernetes" (WeAreDevelopers, Berlin 2026) and the new "Slurm Already Solved This: Teaching Kueue to Schedule License Tokens on Kubernetes", submitted to KubeCon + CloudNativeCon Europe 2027 and Bio-IT World 2027.

WeAreDevelopers World Congress 2026 - Europe
Berlin, Germany
2026
Cloud Native Days
Bologna, Italy
2026
Container Days
London, UK
2026
KCD New York
New York, USA
2025
Container Days
Hamburg, Germany
2025
Voxxed Days
Luxembourg, Luxembourg
2025
Cloud Native Days
Luxembourg, Luxembourg
2024
View Full Speaker Profile →
sessionize.com/hajed-khlifi

Academic Background

🎓
Masters of Cloud architecture Engineering - Evening courses
Esprit University - Tunis, Tunisia
2019 – 2022
🎓
Bachelor's Degree in Computer Systems & Networking
University of Monastir · Monastir, Tunisia
2016 – 2019
🎓
Bachelor's Degree in Mathematics
Lessouda Superior school
2013 – 2016

Get in Touch

Looking for a GPU infrastructure architect or Kubernetes expert? I'm available for freelance consulting engagements across Europe.

✉
📍
Location
Luxembourg, Luxembourg
🔗
💻
Availability
Open to freelance consulting contracts across the EU. Available for remote engagements with on-site support as needed. Short-term architecture reviews to long-term platform delivery.

Or email me directly at kh.hajed@gmail.com